nemorad52742/joshwright-aiavatar 🖼️🔢❓📝✓ → 🖼️
Performance
16.3sTypical run time
8Total runs
About

Example Output
Prompt:
"A hyper-realistic mid-torso portrait of josh, wearing a fitted t-shirt that says mental health , and a plain camoflauge ball cap. seated in the woods on a fallen tree. slight smile in facial expression, framed like a selfie-style content video with shoulders in view. Cinematic realism, shallow depth of field, realistic lens effect, natural skin texture."
Output
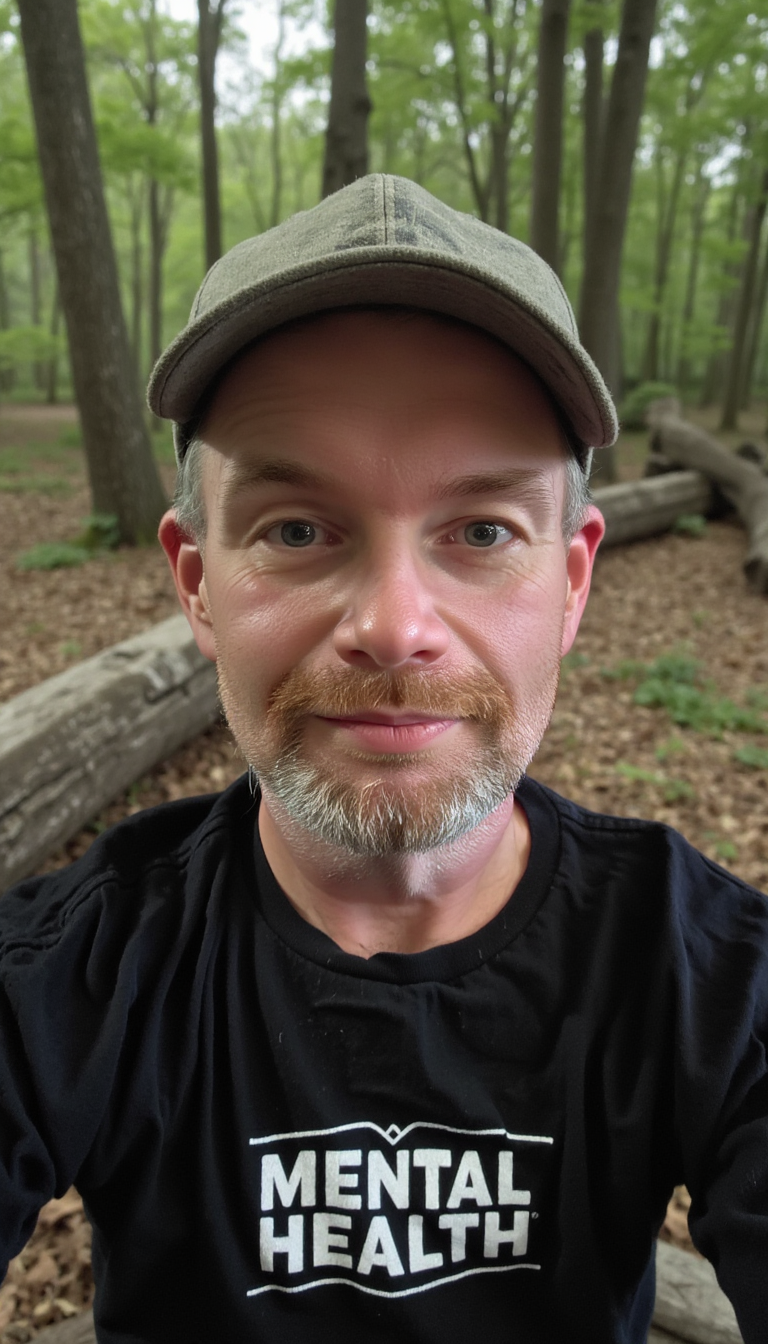
Performance Metrics
16.33s
Prediction Time
21.18s
Total Time
All Input Parameters
{
  "model": "dev",
  "prompt": "A hyper-realistic mid-torso portrait of josh, wearing a fitted t-shirt that says mental health , and a plain camoflauge ball cap. seated in the woods on a fallen tree. slight smile in facial expression, framed like a selfie-style content video with shoulders in view.  Cinematic realism, shallow depth of field, realistic lens effect, natural skin texture.",
  "go_fast": false,
  "lora_scale": 1,
  "megapixels": "1",
  "num_outputs": 2,
  "aspect_ratio": "9:16",
  "output_format": "png",
  "guidance_scale": 3,
  "output_quality": 80,
  "prompt_strength": 0.8,
  "extra_lora_scale": 1,
  "num_inference_steps": 28
}
Input Parameters
- mask
- Image mask for image inpainting mode. If provided, aspect_ratio, width, and height inputs are ignored.
- seed
- Random seed. Set for reproducible generation
- image
- Input image for image to image or inpainting mode. If provided, aspect_ratio, width, and height inputs are ignored.
- model
- Which model to run inference with. The dev model performs best with around 28 inference steps but the schnell model only needs 4 steps.
- width
- Width of generated image. Only works if `aspect_ratio` is set to custom. Will be rounded to nearest multiple of 16. Incompatible with fast generation
- height
- Height of generated image. Only works if `aspect_ratio` is set to custom. Will be rounded to nearest multiple of 16. Incompatible with fast generation
- prompt (required)
- Prompt for generated image. If you include the `trigger_word` used in the training process you are more likely to activate the trained object, style, or concept in the resulting image.
- go_fast
- Run faster predictions with model optimized for speed (currently fp8 quantized); disable to run in original bf16
- extra_lora
- Load LoRA weights. Supports Replicate models in the format <owner>/<username> or <owner>/<username>/<version>, HuggingFace URLs in the format huggingface.co/<owner>/<model-name>, CivitAI URLs in the format civitai.com/models/<id>[/<model-name>], or arbitrary .safetensors URLs from the Internet. For example, 'fofr/flux-pixar-cars'
- lora_scale
- Determines how strongly the main LoRA should be applied. Sane results between 0 and 1 for base inference. For go_fast we apply a 1.5x multiplier to this value; we've generally seen good performance when scaling the base value by that amount. You may still need to experiment to find the best value for your particular lora.
- megapixels
- Approximate number of megapixels for generated image
- num_outputs
- Number of outputs to generate
- aspect_ratio
- Aspect ratio for the generated image. If custom is selected, uses height and width below & will run in bf16 mode
- output_format
- Format of the output images
- guidance_scale
- Guidance scale for the diffusion process. Lower values can give more realistic images. Good values to try are 2, 2.5, 3 and 3.5
- output_quality
- Quality when saving the output images, from 0 to 100. 100 is best quality, 0 is lowest quality. Not relevant for .png outputs
- prompt_strength
- Prompt strength when using img2img. 1.0 corresponds to full destruction of information in image
- extra_lora_scale
- Determines how strongly the extra LoRA should be applied. Sane results between 0 and 1 for base inference. For go_fast we apply a 1.5x multiplier to this value; we've generally seen good performance when scaling the base value by that amount. You may still need to experiment to find the best value for your particular lora.
- replicate_weights
- Load LoRA weights. Supports Replicate models in the format <owner>/<username> or <owner>/<username>/<version>, HuggingFace URLs in the format huggingface.co/<owner>/<model-name>, CivitAI URLs in the format civitai.com/models/<id>[/<model-name>], or arbitrary .safetensors URLs from the Internet. For example, 'fofr/flux-pixar-cars'
- num_inference_steps
- Number of denoising steps. More steps can give more detailed images, but take longer.
- disable_safety_checker
- Disable safety checker for generated images.
Output Schema
Output
Example Execution Logs
free=16390338949120
Downloading weights
2025-09-24T19:14:45Z | INFO  | [ Initiating ] chunk_size=150M dest=/tmp/tmp2cu3ht_p/weights url=https://replicate.delivery/xezq/2F2Zb6kQe6UocqfMPauYbjOFdeWiqyHtyrjUONDK45V1WOrqA/trained_model.tar
2025-09-24T19:14:45Z | INFO  | [ Cache Service ] enabled=true scheme=http target=hermes.services.svc.cluster.local
2025-09-24T19:14:45Z | INFO  | [ Cache URL Rewrite ] enabled=true target_url=http://hermes.services.svc.cluster.local/replicate.delivery/xezq/2F2Zb6kQe6UocqfMPauYbjOFdeWiqyHtyrjUONDK45V1WOrqA/trained_model.tar url=https://replicate.delivery/xezq/2F2Zb6kQe6UocqfMPauYbjOFdeWiqyHtyrjUONDK45V1WOrqA/trained_model.tar
2025-09-24T19:14:45Z | INFO  | [ Redirect ] redirect_url=http://r8-east4-loras-ric1.cwlota.com/1fa6bb36376f777bb07f55197b024b32e1159ca327463b679fb20a380c6b7879?X-Amz-Algorithm=AWS4-HMAC-SHA256&X-Amz-Checksum-Mode=ENABLED&X-Amz-Credential=CWNZUVKLDHXVHEZN%2F20250924%2FUS-EAST-04A%2Fs3%2Faws4_request&X-Amz-Date=20250924T191445Z&X-Amz-Expires=600&X-Amz-SignedHeaders=host&x-id=GetObject&X-Amz-Signature=70888460d4999611a738c1777aaa154ae3dc85dcf19192a58937bfc5ce794b8f url=http://hermes.services.svc.cluster.local/replicate.delivery/xezq/2F2Zb6kQe6UocqfMPauYbjOFdeWiqyHtyrjUONDK45V1WOrqA/trained_model.tar
2025-09-24T19:14:45Z | INFO  | [ Complete ] dest=/tmp/tmp2cu3ht_p/weights size="172 MB" total_elapsed=0.282s url=https://replicate.delivery/xezq/2F2Zb6kQe6UocqfMPauYbjOFdeWiqyHtyrjUONDK45V1WOrqA/trained_model.tar
Downloaded weights in 0.34s
Loaded LoRAs in 1.32s
Using seed: 52098
Prompt: A hyper-realistic mid-torso portrait of josh, wearing a fitted t-shirt that says mental health , and a plain camoflauge ball cap. seated in the woods on a fallen tree. slight smile in facial expression, framed like a selfie-style content video with shoulders in view.  Cinematic realism, shallow depth of field, realistic lens effect, natural skin texture.
[!] txt2img mode
  0%|          | 0/28 [00:00<?, ?it/s]
  4%|▎         | 1/28 [00:00<00:13,  2.02it/s]
  7%|▋         | 2/28 [00:00<00:11,  2.28it/s]
 11%|█         | 3/28 [00:01<00:11,  2.14it/s]
 14%|█▍        | 4/28 [00:01<00:11,  2.09it/s]
 18%|█▊        | 5/28 [00:02<00:11,  2.06it/s]
 21%|██▏       | 6/28 [00:02<00:10,  2.04it/s]
 25%|██▌       | 7/28 [00:03<00:10,  2.03it/s]
 29%|██▊       | 8/28 [00:03<00:09,  2.02it/s]
 32%|███▏      | 9/28 [00:04<00:09,  2.01it/s]
 36%|███▌      | 10/28 [00:04<00:08,  2.01it/s]
 39%|███▉      | 11/28 [00:05<00:08,  2.01it/s]
 43%|████▎     | 12/28 [00:05<00:07,  2.00it/s]
 46%|████▋     | 13/28 [00:06<00:07,  2.00it/s]
 50%|█████     | 14/28 [00:06<00:06,  2.00it/s]
 54%|█████▎    | 15/28 [00:07<00:06,  2.00it/s]
 57%|█████▋    | 16/28 [00:07<00:05,  2.00it/s]
 61%|██████    | 17/28 [00:08<00:05,  2.00it/s]
 64%|██████▍   | 18/28 [00:08<00:04,  2.00it/s]
 68%|██████▊   | 19/28 [00:09<00:04,  2.00it/s]
 71%|███████▏  | 20/28 [00:09<00:03,  2.00it/s]
 75%|███████▌  | 21/28 [00:10<00:03,  2.00it/s]
 79%|███████▊  | 22/28 [00:10<00:03,  2.00it/s]
 82%|████████▏ | 23/28 [00:11<00:02,  2.00it/s]
 86%|████████▌ | 24/28 [00:11<00:02,  2.00it/s]
 89%|████████▉ | 25/28 [00:12<00:01,  2.00it/s]
 93%|█████████▎| 26/28 [00:12<00:01,  2.00it/s]
 96%|█████████▋| 27/28 [00:13<00:00,  2.00it/s]
100%|██████████| 28/28 [00:13<00:00,  2.00it/s]
100%|██████████| 28/28 [00:13<00:00,  2.02it/s]
Total safe images: 2 out of 2
Version Details
- Version ID
9fa9a851ab1ac8cbe2eba33750a95fdfcc7782424a9239255ede4748255b2ebe- Version Created
- September 16, 2025