🤖 Model 🖼️ → 🖼️
qwen/qwen-image-edit-plus
Edit one or more images from a text instruction to produce a new image. Combine multiple inputs (person + person, person...
Found 1851 models (showing 1081-1100)
Edit one or more images from a text instruction to produce a new image. Combine multiple inputs (person + person, person...
Generate images from text prompts, with optional image editing via inpainting and ControlNet-guided generation. Conditio...
Generate images from text prompts. Optionally transform an input image or inpaint masked regions guided by the prompt. U...

Generate images in the FLASH artistic style from a text prompt. Optionally stylize an input image or fill masked regions...
Generates images of a person called yagyesh4 based on text prompts. The trigger word for this LoRA fine-tune is 'yagyesh...

Generate images in the CRAISEE artistic style from a text prompt. Optionally transform an input image (img2img) or fill...

Generate images from text prompts using a customizable diffusion model that supports text-to-image, image-to-image, and...
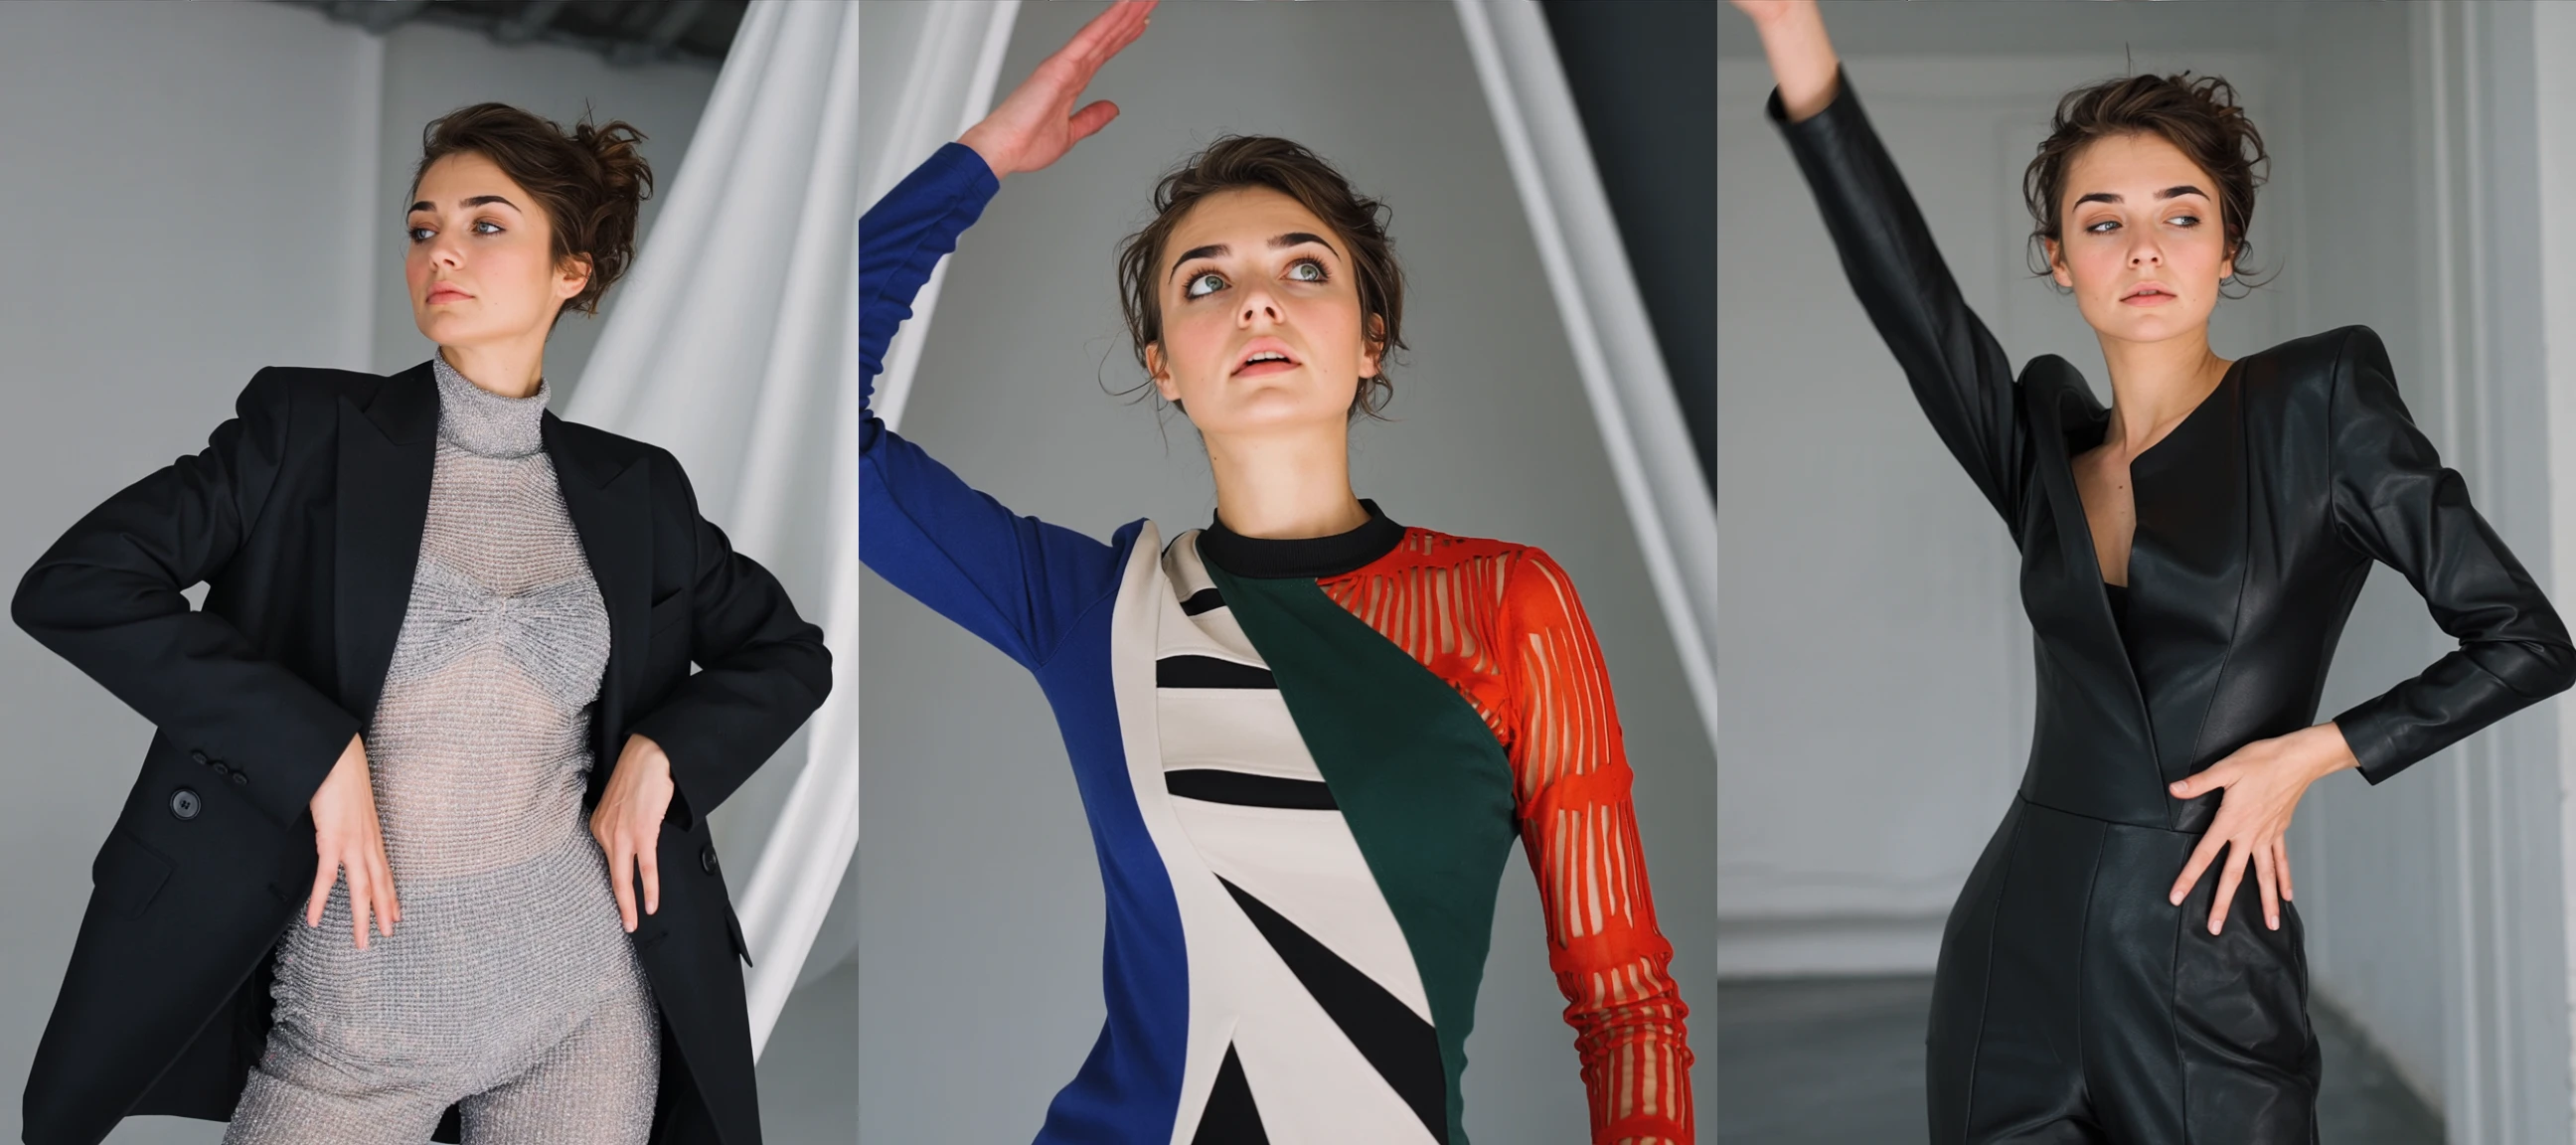
Generate consistent character images from a single reference photo and a text prompt. Maintain the subject’s identity ac...
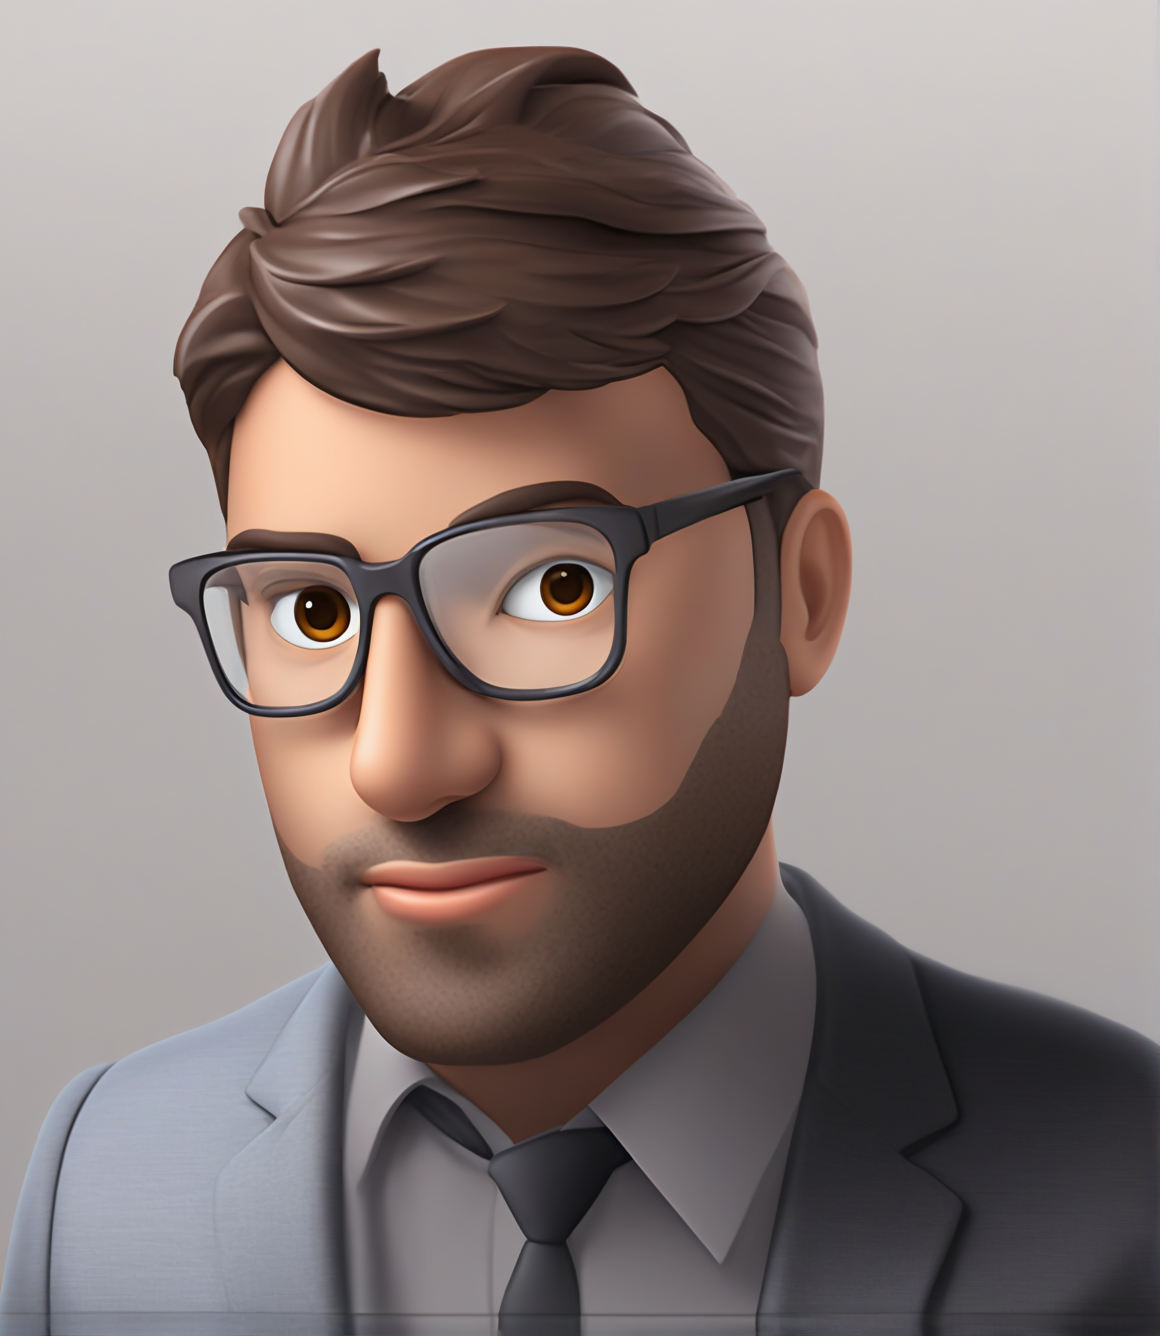
Convert photos into emoji-style avatars from an input image and text prompt. Generate cartoon/emoji portraits and icons...

Generates images from text prompts with support for image-to-image transformation and inpainting. Supports multiple sche...
Generate emoji‑style icons from text prompts as images. Optionally convert an input image or edit with a mask to create...
Generates cute mascot avatars from text prompts. Fine-tuned SDXL model specialized for creating cartoon-style character...
Generate images with an early-2000s "bad 2004 digital camera" aesthetic from a text prompt. Optionally input an image to...

Generate emoji-style images from a text prompt. Optionally use an input image or a mask for image-to-image and inpaintin...
Virtual try-on model that allows users to see how garments look on people by taking an image of a person, a garment imag...
Generate fursuit convention images from a text prompt. Create anthropomorphic furry characters, fursuit portraits, and c...
Transform an input image into a stylized output guided by a text prompt. Takes a reference image (optionally a second re...
Virtually tries on clothing items by taking an image of a person and an image of a garment, returning a realistic image...
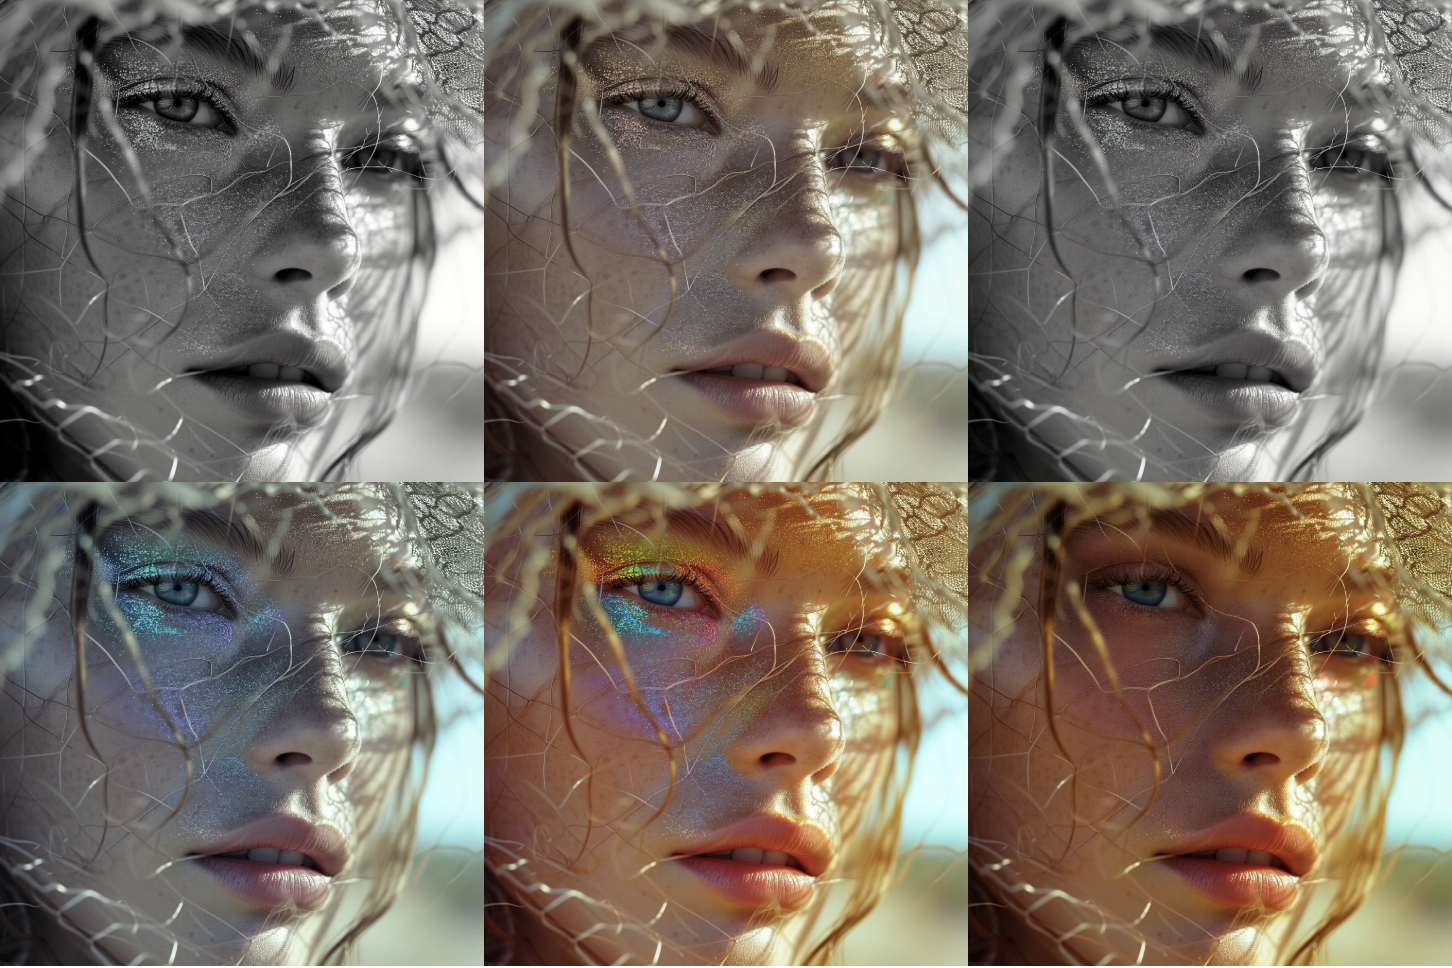
Applies simple image filters to input images using FLUX Kontext. Supports six filter options: Vivid, Black and White, Se...

Generate images of Caribbean characters from text prompts. Optionally provide an input image for image-to-image translat...