🤖 Model 🖼️
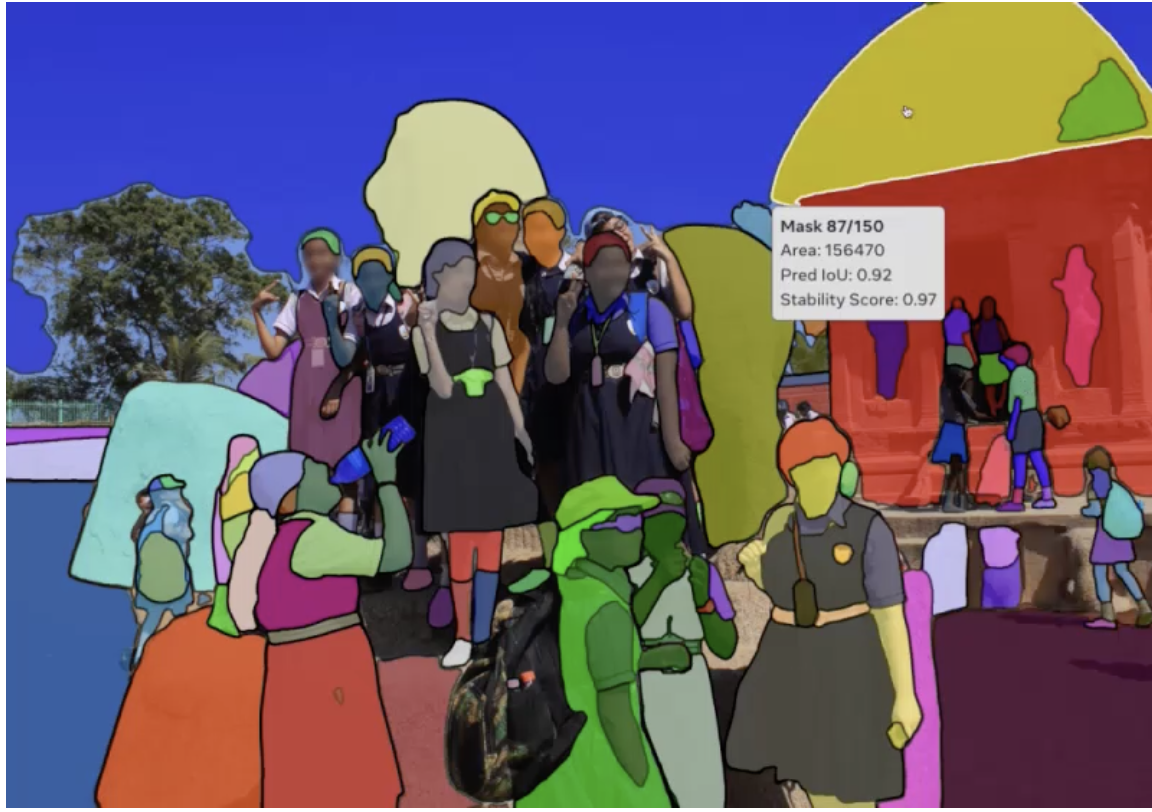
cbx1/sam-vit-h
Converts images into vector embeddings using the Segment Anything Model (SAM) vision transformer. Uses a foundation mode...
Found 2 models (showing 1-2)
Converts images into vector embeddings using the Segment Anything Model (SAM) vision transformer. Uses a foundation mode...
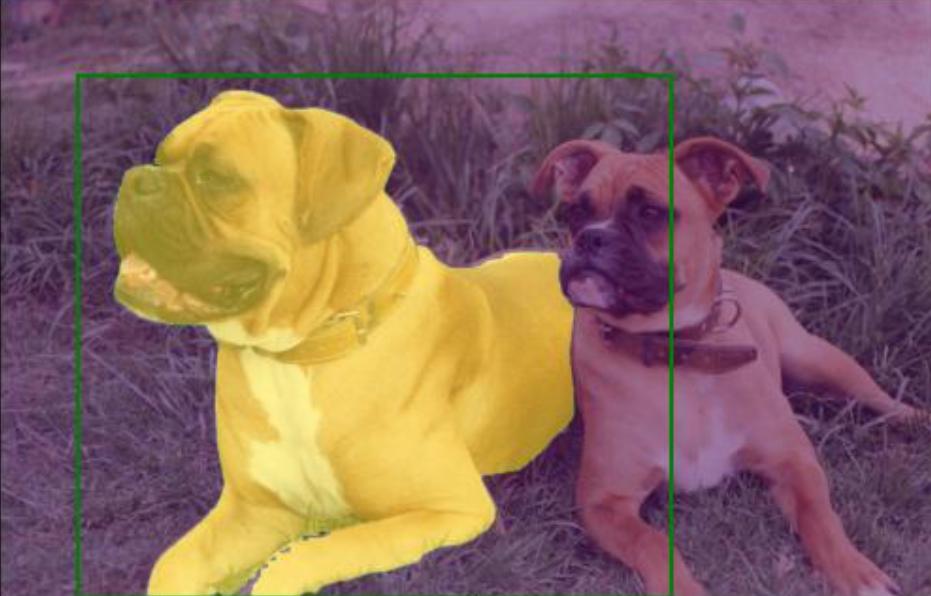
Segments objects in images using a highly-accelerated version of the Segment Anything Model (SAM) optimized for edge dev...